Rebuild Staging From Production Backups
Before each release, I rebuild staging from the latest production backup. The release gets tested on real data shapes, and the restore process gets tested too.
A staging environment with fake data only catches fake problems. Real data has odd values, old records, and shapes nobody planned for.
On RE/AMP I rebuild staging from the latest production backup before each release. That choice does two jobs at once.
The problem
Most release bugs I have seen come from data, not logic. A field that is always filled in test data turns out to be empty in old records, or a migration meets a row it did not expect.
Backups have a second problem. A backup nobody restores is a hope, not a plan.
What I do
- Restore the latest production database backup into staging.
- Sync the storage files for staging from production.
- Deploy the release to staging.
- Test it against that real snapshot, isolated from production.
- Merge to the stable branch and deploy to production.
Fixes land on staging first, then move to the stable branch for production deploys.
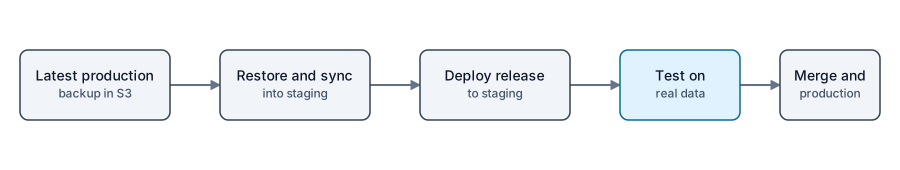
Restore, deploy, test, then promote.
Why backups are built for restoring
I use directory-format dumps with pg_dump and pg_restore and a parallel job count, rather than single-file dumps. That allows several workers to restore at once and lets me recover individual tables if I need to.
Backups go to S3 on a schedule, and a second copy stays on a separate local disk.
The recovery benefit
Because I restore from backup on every release, the recovery process is exercised constantly. If production fails, the path is already familiar: restore the latest backup into a working environment, point traffic at it, and rebuild.
I would rather find a broken restore step on a normal Tuesday than during an outage.
The tradeoff I chose
The staging rebuild is on demand, not on a cron job. Staging only needs to be fresh right before a release, so a constant refresh would cost compute and time for no benefit.
What I would do differently
As the team grows past a small group, the process needs more formality: written steps, named owners, and checks that do not depend on one person’s memory.
Takeaway
Test your releases on real data shapes, and test your restores often. Doing both in one step makes it cheap enough that it actually happens.
For help setting up a release process like this, see the custom web applications service or the RE/AMP case study.