Phone Scrubber Rate-Limited Queue Case Study
Cleaning phone lists through an API that limits how fast you can ask
Phone lists go stale. Numbers are disconnected, wrong, or not worth calling first, and a team that dials them in the wrong order wastes time.
I built a phone scrubber at Aquifer Investments that checks a list through the Trestle API and returns a cleaned file the team could use to rank who to call.
The problem
The business worked from lists where each row was one person, with up to 30 phone numbers attached. Checking that many numbers by hand was not realistic, and the checking service is an outside API with its own limits.
What the API returned
For each number, Trestle returned activity levels, validity, and phone type, along with a lot more. The business mostly used those fields to rank phones for outbound contact. A number with strong activity and a valid line goes near the top of the list.
The constraint
The API’s rate limit was low, on the order of ten requests per second as I remember it. There was no batch endpoint, so every number was its own request.
A file of 100 rows with up to 30 phones each is up to 3,000 requests. Sending them all at once would break the limit, so the app had to control the pace whatever the file size.
What I built
- Upload. A user uploads a CSV in the browser.
- Queue. The phones are fed into a rate-limited queue that sends requests to Trestle at a pace the service allows.
- Fan in. The results are collected and matched back to the right row and the right phone.
- Export. The user downloads a cleaned CSV.
The app is written in Python and Django, with MySQL for data and HTMX for a light, server-rendered interface.
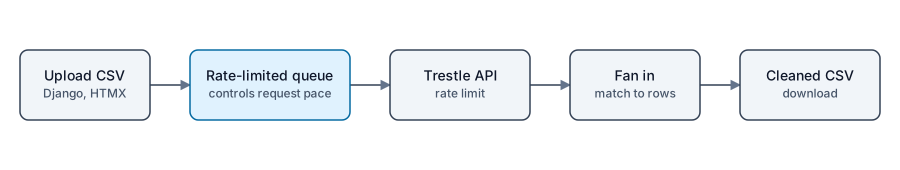
The queue sets the request pace, so file size changes duration and not success.
Row order had to survive
Each row represented one person, and the order of rows had to be preserved. An upload looked like name, address, phone 1, phone 2, and so on up to phone 30.
The export kept the same shape and added the results next to each number: name, address, phone 1, phone 1 activity, phone 1 type, phone 1 status, then the same for phone 2. Because the queue returns results out of order, matching each result back to its row and phone slot was a real part of the work.
When the API fails
If the API fails for a phone, that phone simply does not get the new information. It is labeled as an error or failed, and the reason from the API, or the error itself, is stored in the database. The rest of the file keeps going.
That means a partial failure never blocks a whole upload, and a person can see exactly which numbers were not checked and why.
Why a queue
A queue turns a hard limit into a predictable job. The size of the upload changes how long the job takes, not whether it succeeds.
The same idea works for any outside service that restricts how fast you can call it. It also gives you one place for logging and progress display.
What I do not claim
I have no throughput or accuracy figures to publish. The rate limit above is from memory, so treat it as an order of magnitude and not as a specification.
Related
This project is an example of the API integrations and data pipelines and automation services.